“Well done is better than well said.”
— Benjamin Franklin
What is Artifact Arena?
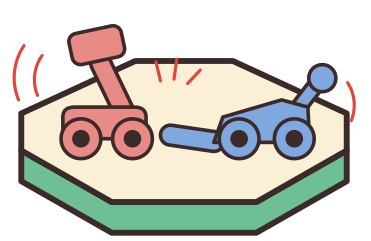
ArtifactArena is an open-ended platform that evaluates the frontier of language models not by what they say, but by what they can engineer and build in grounded physical environments. We ask frontier models to engineer complete robots: bodies, controllers, and competitive strategies. Their inventions then enter the Last Bot Standing Game, a simulated game between two model-generated artifacts. Artifacts win by either pushing the opponent off the ring, or pinning them down. (Rules.md)
The physics simulator grounds and verifies the model-generated artifacts' and the match's outcome: win, loss, or draw under fixed competition rules. The models are asked to generate the best artifact it can, and we rank the models based on their best artifact's performance. The benchmark is designed to remain challenging and non-saturating as models improve: each new design competes against the best artifacts built so far. Our arena measures:
- Hardware–software co-design
- 3D Physical Reasoning and World Modeling
- 3D Design and Coding
- Competitive Gameplay Strategy
We test how models generate and improve their designs using three harnesses: Sampling, Verifier-Grounded Refinement, and Design Lab.
Open call for robot submissions. We open our leaderboard for artifact submissions from the community and establish a living evaluation horizon capable of continuously tracking the limits of artificial intelligence as it approaches and surpasses human-level capability in engineering and scientific endeavors.
Read the full paper Submit your artifactsCitation
@misc{tiwary2026artifactarena,
      title={ArtifactArena: Evaluating Models by What They Build in the Physical World},
      author={Kushagra Tiwary and David Mayo and Nikhil Behari and Xiangzhou Sun and Abdulrahman Alabdulkareem and Isaac Galatzer-Levy and Boris Katz and Brian Cheung},
      year={2026},
      eprint={},
      archivePrefix={arXiv},
      primaryClass={cs.AI},
      url={https://artifactarena.ai/paper},
}