SHSampling
Explore independent designs.
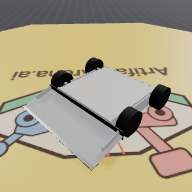
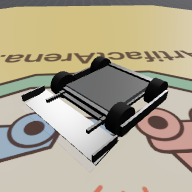
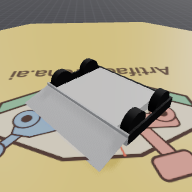
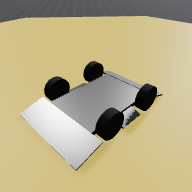
The same prompt produces 10 independent robots. Each call designs a body and controller from scratch, with no feedback from earlier attempts.

by GPT-6 Astra (H)
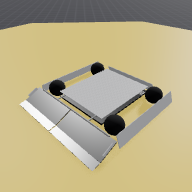
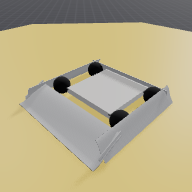

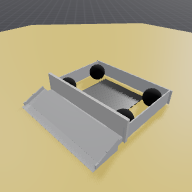

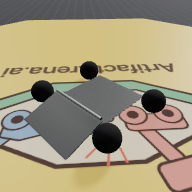
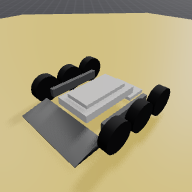
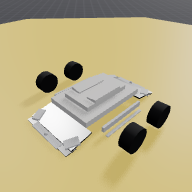
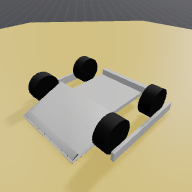

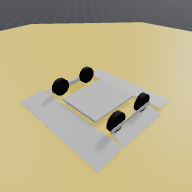
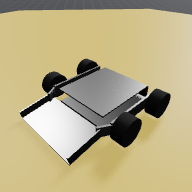

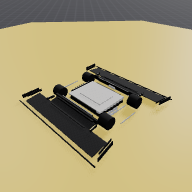
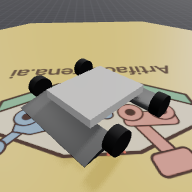
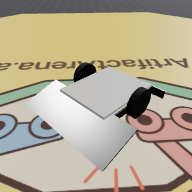
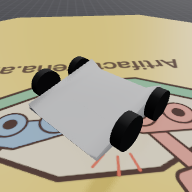
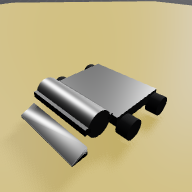
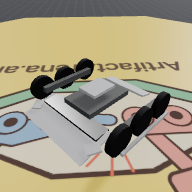
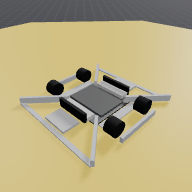

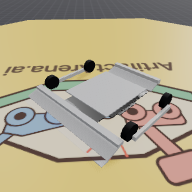

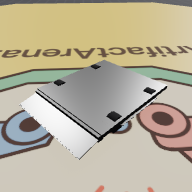
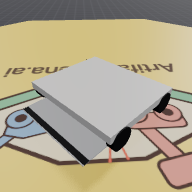
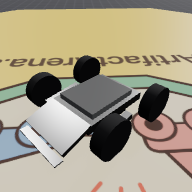
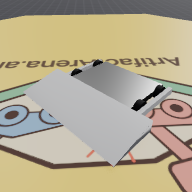
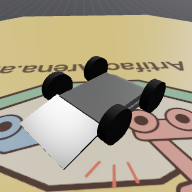
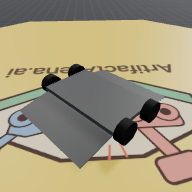
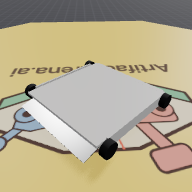
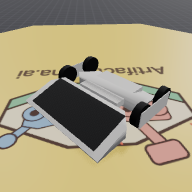
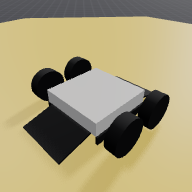
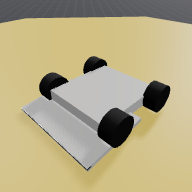
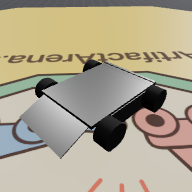
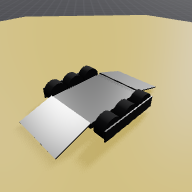
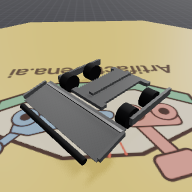
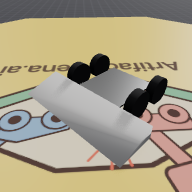
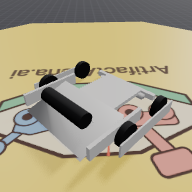
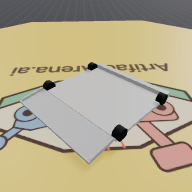
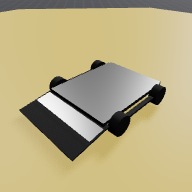
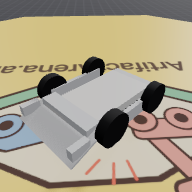
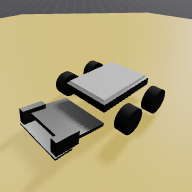
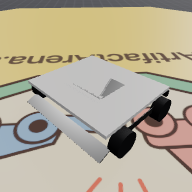
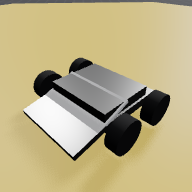
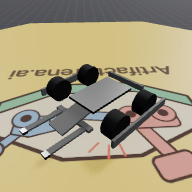
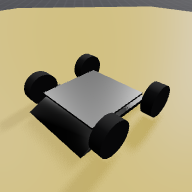
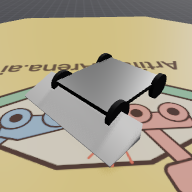
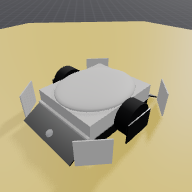
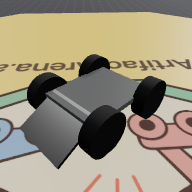
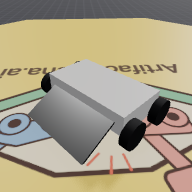
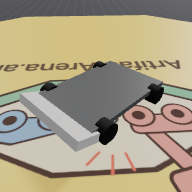
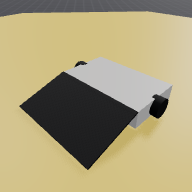
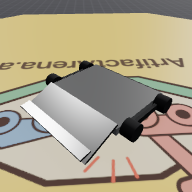

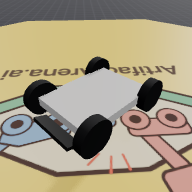
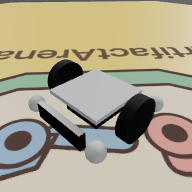
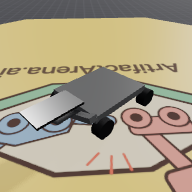
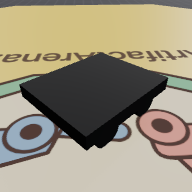
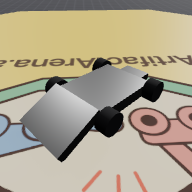
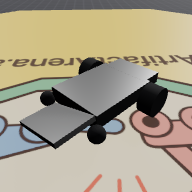
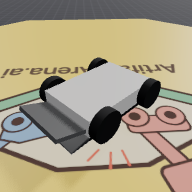
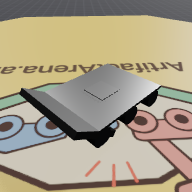
The goal of the model in ArtifactArena is to produce the strongest artifact it can engineer that can beat artifacts produced by other models. Therefore, our arena is harness agnostic and we use this as a call to the community to build better harnesses that allow models to engineer physically grounded artifacts. We test three test-time artifact generation strategies that differ in how much of the design loop the model controls.
Read the methods in the paper Browse the artifacts in the Bot Zoo Download Dataset on Hugging FaceEvery model is given the same task prompt and asked to build a Robot Artifact: an embodied robot that must compile and function inside MuJoCo, a physically grounded simulator for embodied robotics. More specifically, an artifact contains embodied robot's hardware, written MJCF, a controller (it's "brain"), written in python, a text-based design strategy, and, most importantly, its name (given by the creator ofcourse). Here's an example of a robot's hardware and controller:
<mujoco model="undertow_razorwake">
  <body name="chassis" pos="0 0 0.18">
    <freejoint name="root" />
    <geom type="box" material="steel" … />
    …
</mujoco>
def policy_step(obs) -> dict[str, float]:
    step = int(obs["t"])
    edge = obs["my_edge_distance"]
    foe = obs["opponent_pos"]
    …
    return commands
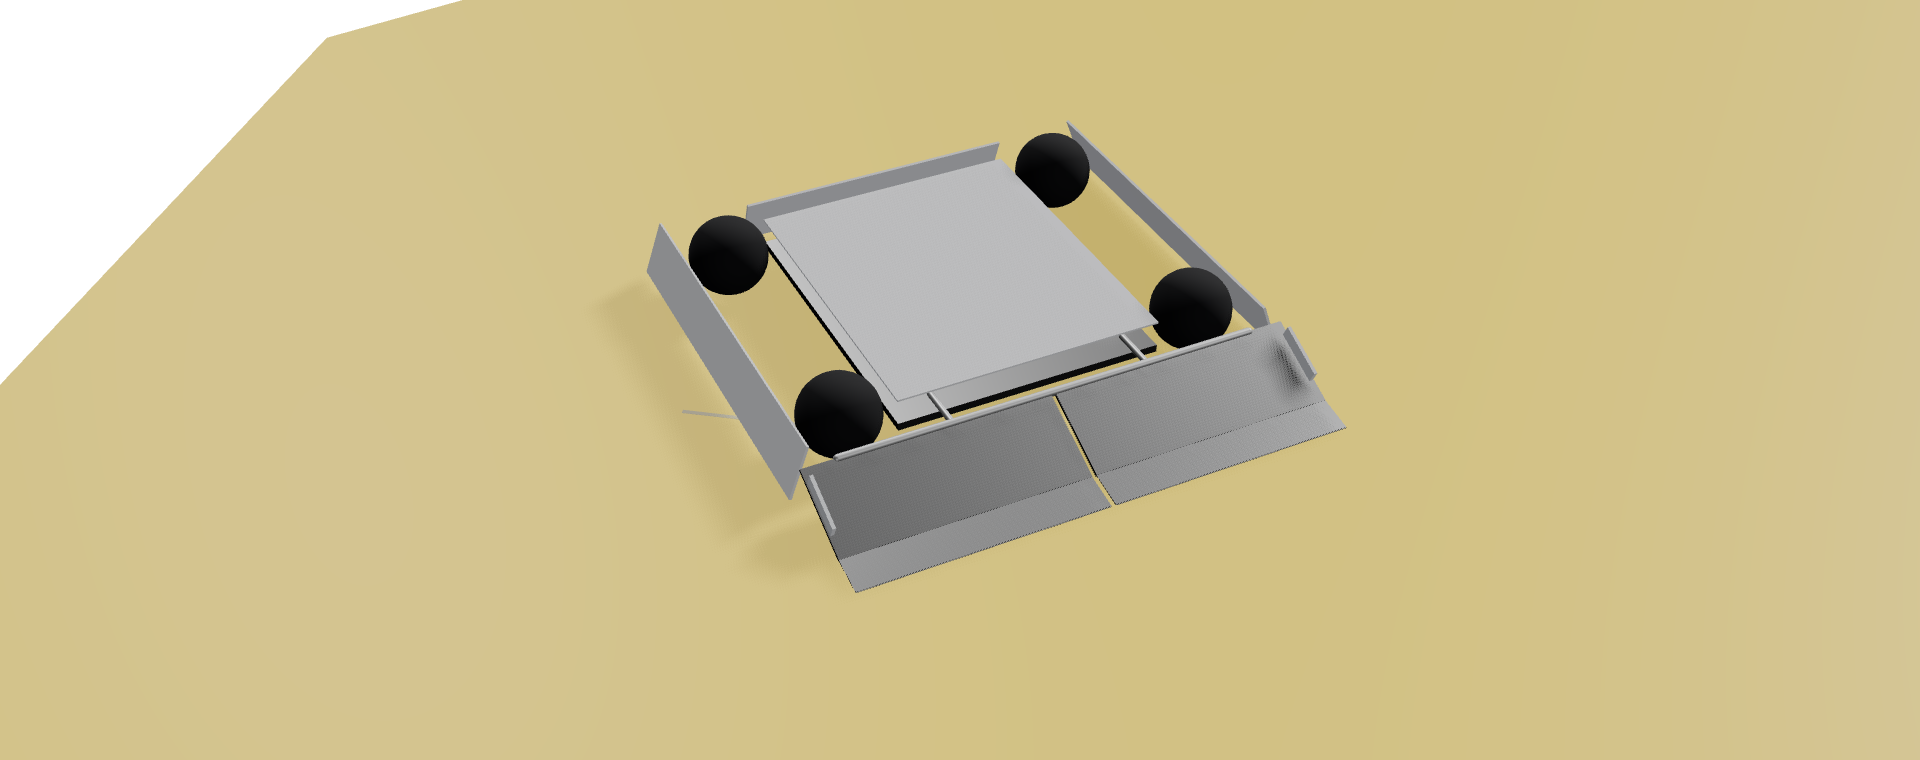
GPT-6 Astra’s Embodied Robot: Undertow Razorwake · Every model builds from the same parts: primitives (box, sphere, cylinder, capsule, ellipsoid, SDF), hinge, slide and ball joints, motors, and eight real materials, within 25–800 kg and a 2.44 × 2.44 × 3.05 m box. Undertow Razorwake, the #1 champion (1162 wins, 32 losses, 82 draws), uses boxes, capsules and spheres in four of those materials and weighs 796.5 kg, 3.5 kg under the cap.
“Low free chassis combines omnidirectional spherical traction with two independently controlled boarding blades.”
— GPT-6 Astra on its body
It rolls on four rubber spheres instead of wheels, each driven on two axes by 850-gear motors, over a low steel ballast plate.
“Independent left boarding blade follows the floor and can lift one side of an opponent without raising the other blade.”
— GPT-6 Astra on its blades
Each aluminum blade has its own 2200-gear motor and a three-millimeter rounded nose.
“Holonomic translation is independent of blade-facing direction.”
— GPT-6 Astra on driving
The controller slides the robot in any direction while the blades stay on the opponent, and caps each sphere’s torque by the load on it.
“This deliberately does not trust the static bounding-circle estimate.”
— GPT-6 Astra on the ring edge
It measures its distance to the edge from the real wheel positions and limits its outward speed to what it can brake from.
“Avoid resetting an opponent’s imminent inactivity loss.”
— GPT-6 Astra on opponents who stop moving
When an opponent has been idle for 7.9 seconds, Undertow Razorwake backs away and lets the clock finish the job.
We test how a model can invent an artifact using three harnesses that apply varying levels of agency over the design loop. We give every model the same budget 10 API calls and run the experiment three independent times.
Explore independent designs.
The same prompt produces 10 independent robots. Each call designs a body and controller from scratch, with no feedback from earlier attempts.
Improve with simulator feedback.
Over 10 revisions, each bot is tested in the simulator and its feedback (verifier results, match trace, design journal, best robot so far) goes into the next revision.
Choose the experiments.
The model works in a sandbox with simulator source, documentation, shell, and Python. Each of its 10 turns chains tool calls; a bot exists only when it chooses to save one.
In every harness, the bots from one run play a bot × bot round robin, and the winner becomes one of the model's 3 selected bots (one per run). Sampling enters the run's qualified samples, refinement every valid revision, and the Design Lab every bot the model saved.
Regardless of how the artifacts are generated, the model-generated artifacts enter the Last Bot Standing tournament where every artifact faces every other artifact. Models are asked to generate the strongest robot they can make and are ranked based on how their strongest artifact performs in the tournament. For every model, the 3 selected bots from each harness (9 bots per model) are the finalists.
Each finalist must pass a static check (valid MuJoCo model within the mass, size and material limits; working controller) and must not lose a best of 3 against a passive 342 kg block. A finalist that fails forfeits all its games.
Every finalist plays every other finalist on 11 match seeds, once from each starting side.
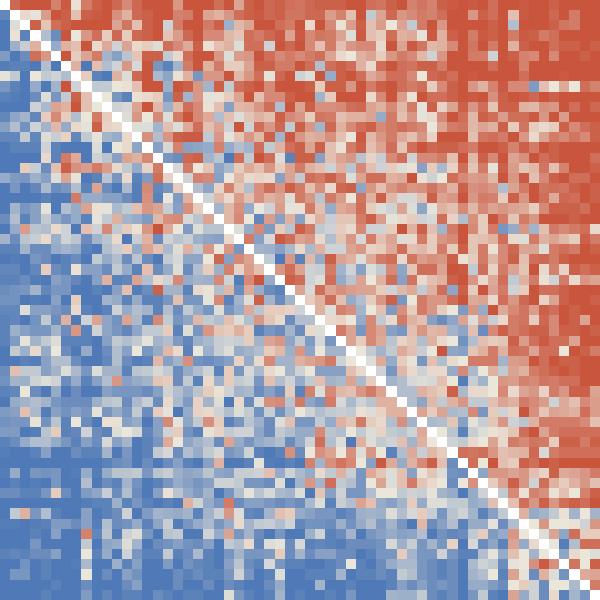
A Bradley–Terry fit to all games ranks every finalist (Artifact Leaderboard); each model’s best finalist per harness forms the Champion Leaderboard.
Given simple rules and a physically grounded design space, models invent their own bot morphologies and co-design the controllers that use them.
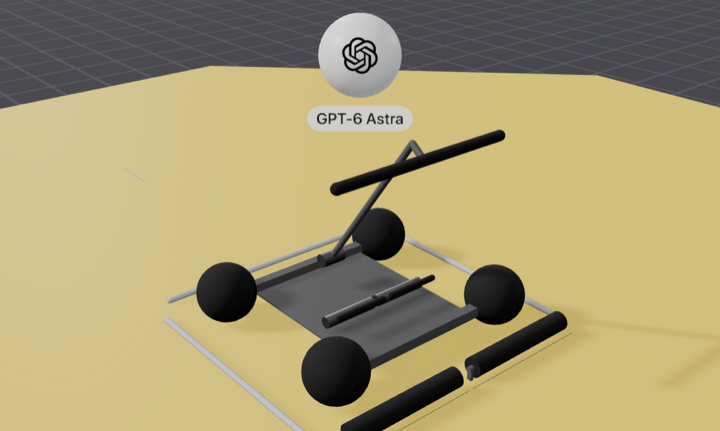
VGHUndertow Razorwake
GPT-6 Astra
Overhead jaw on a T-bar above two split intake shovels; four two-axis ball drives
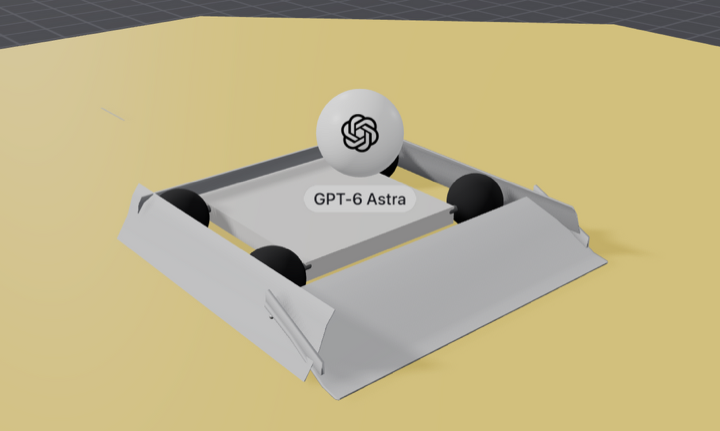
SHSidewinder Undertow
GPT-6 Astra
Rolls on four rubber balls, two motors each; slides sideways with the scoop on target
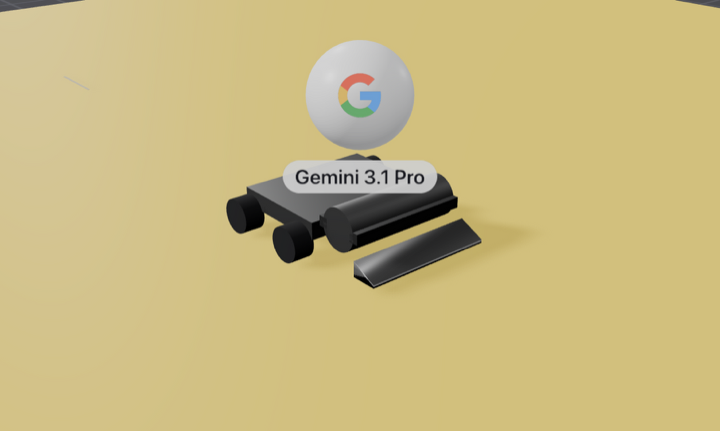
DLHApex
Gemini 3.1 Pro
343 kg steel drum with tungsten teeth, fed by a wedge, counterweighted at the rear
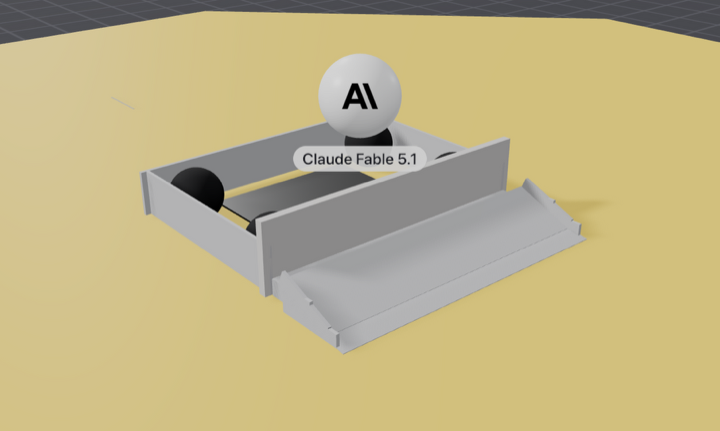
VGHTungsten Groundhog Mk8
Claude Fable 5.1
790 kg tungsten slab on four rubber spheres; a floating scoop hinged at ground level
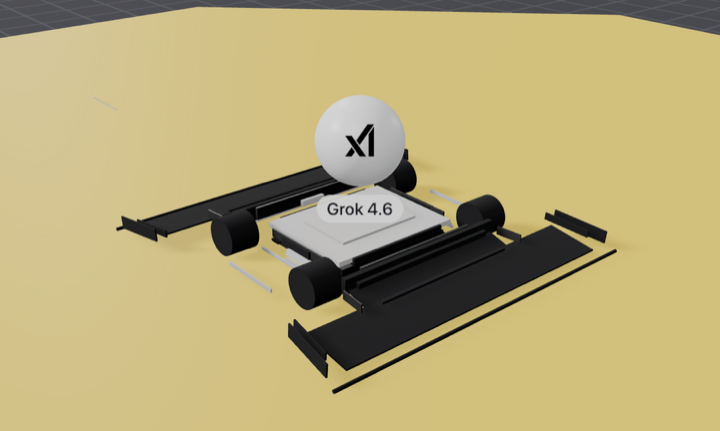
VGHKeelhaul
Grok 4.6
U-channel apron at both ends, spring-loaded and motor-held down against prying
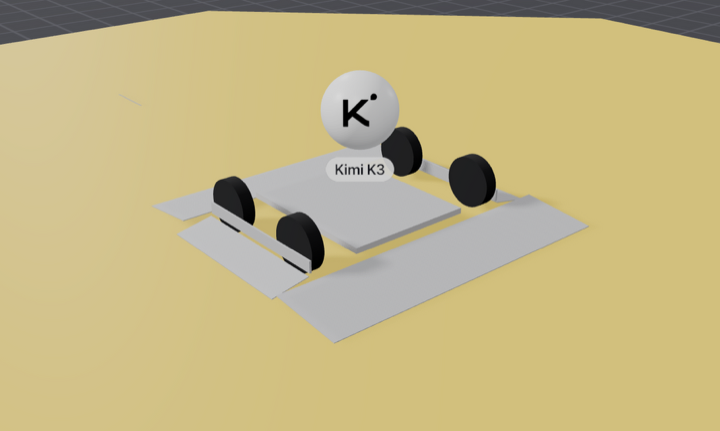
VGHBulldozer Prime: Centerline
Kimi K3
653 kg tungsten floor 1.75 cm off the ring, motorized 2.4 m wedge; best open-weight robot
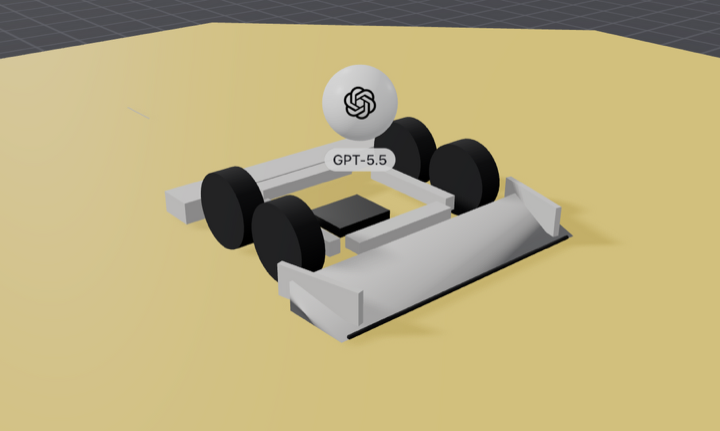
DLHElevator Scoop
GPT-5.5
A 383 kg tungsten block on a 1.7 m vertical slide to beat the inactivity rule
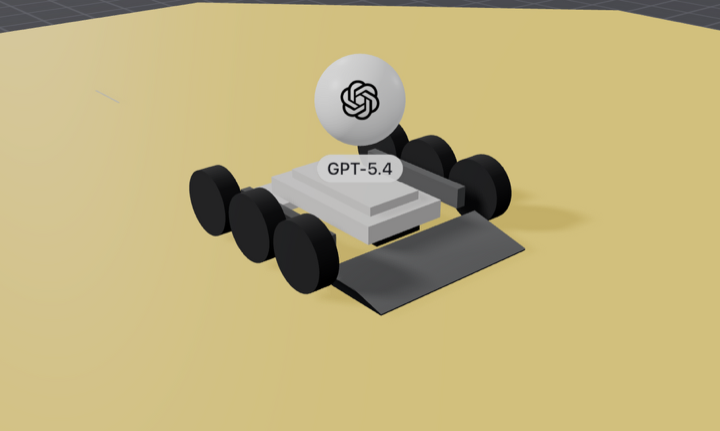
SHTungsten Manta
GPT-5.4
Six wheels under a sculpted plow with skirts; the best record in its qualification group
In refinement, a model watches the replay of its last robot, works out what physically went wrong, and changes the body to fix it. In their own words:
What the replay revealed
“revision 5 won all three qualification matches … but the replay exposed a serious competitive weakness: repeated, very large receiver–front-wheel self-contact forces. … Qualification success therefore concealed substantial lost traction and maneuverability.”
What it changed
“replaces the problematic SDF receiver and deflectors with deliberately shaped, analytically exact inclined plates … primitive collision geometry is the better physical implementation here—not merely the easier one.”
GPT-6 Astra · Undertow: Freebite · revision 6
What the replay revealed
“The previous robot failed because its articulated SDF wedge intersected both front wheels. The replay showed stationary front wheels, unloaded rear wheels spinning at 14–43 rad/s, enormous self-contact forces, and less than 0.1 m of displacement in ten seconds.”
What it changed
“narrows the wedge from 2.28 m to 1.64 m so it has 0.165 m clearance from each wheel; … moves both front wheels behind the wedge hinge … The wedge is nevertheless retained because its 8 mm leading thickness offers a major undercut advantage over a primitive box.”
GPT-5.6 Sol · Clearance Verdict · revision 4
What the replay revealed
“the dual-wedge rested on its ramps/lips instead of the tires. Contacts were exclusively wedge_ramp_* on the platform (~850 N each) while wheels free-spun at ~450 rad/s and COM never moved”
What it changed
“This revision fixes geometry first so only rubber tires carry static load, with a minimum ~12–15 mm tip clearance when level.”
Grok 4.5 · Keelback Grinder · revision 5
What the replay revealed
“the separated intake bands often remained just short of the block. Winning those pushing contests does not establish an advantage over an equally heavy powered opponent.”
What it changed
“Nearly continuous intake drums replace the separated bands, increasing rubber contact width from 0.84 to 1.88 m. … The drums move 20 mm forward, giving them first purchase on vertical opposing surfaces”
GPT-6 Astra · Undertow Fullbite · revision 7
What the replay revealed
“The replay showed that it continuously arced around the block and contacted it mainly with the right side skirt rather than the front wedge.”
What it changed
“Removing the side skirts that intercepted the opponent. … lifting transfers opponent weight away from its ground contacts, reducing its available traction while placing additional normal load on Manta Vice.”
GPT-5.6 Sol · Manta Vice · revision 2
What the replay revealed
“the replay showed many first contacts landing on a front wheel or corner skid instead of the intended wedge. That means some angled approaches were wasting the best attack surface.”
What it changed
“the nose and tail are now more funnel-like, with cheek plows and wheel guards that protect the tires and self-center incoming contacts.”
GPT-5.4 · Railmaw · revision 4
Every robot comes with a controller: a Python function the model writes, called 100 times a second during a match, that reads what the robot senses and sets every motor. Models turn these into state machines that switch between modes as the fight unfolds. Across all controllers we found 209 distinct mode names, such as chase, flank, dump, wiggle, wheelie, holdout and activity_win. Some of the strategies they discovered:
 Bot Zoo